Jev Benchmarks for Review Pipelines
Niels Bantilan benchmarked Jev against a “System 2” approach for customer support, code review, and legal contract review. He reports Jev was up to x2.6 faster and at least x10 cheaper, with no loss in quality.
 Niels Bantilan@niels_ai
🤔 Where do #Jev and other "Decision Models" fit into your current agentic or non-agentic pipelines?
The short answer: anywhere you might have LLM calls with a #pydantic model or json schema to type-cast your raw data into structured categories, Likert-scale numerical scores, or true/false decisions.
I ran three benchmarks with @flyteorg on https://t.co/WczbNQoVLn in the context of three use cases:
- Customer support
- Code review
- Legal contract review
In all three cases, using Jev was faster (up to x2.6) and cheaper (at least x10) with no loss in quality compared to using a "System 2"
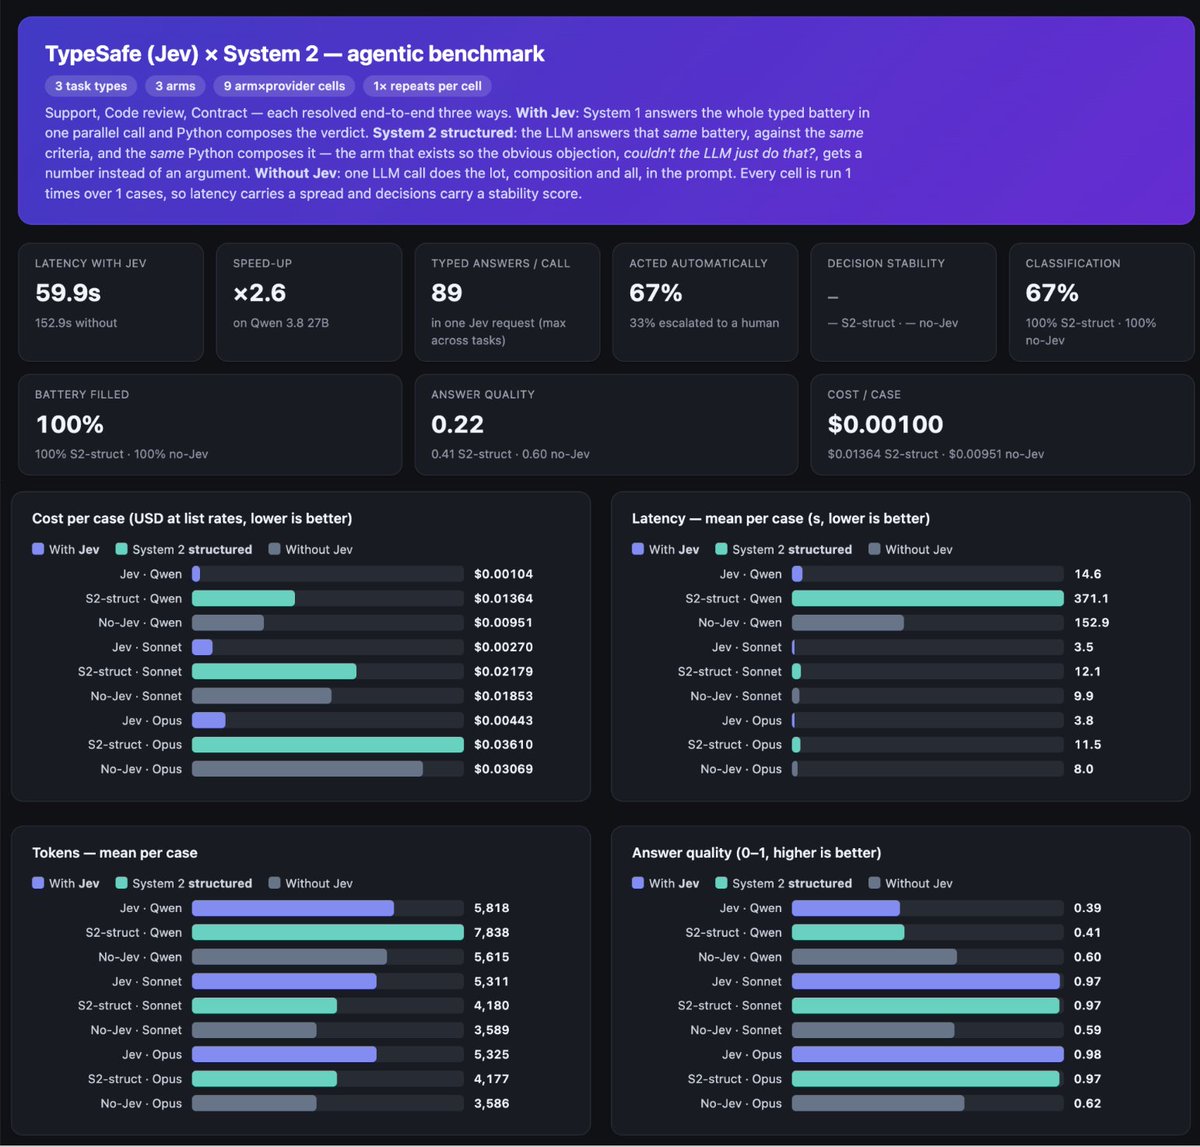
Bantilan ran the benchmarks with Flyte. He describes decision models as suitable for LLM calls that turn raw data into structured categories, Likert-scale scores, or true/false decisions.
Also filed under Triage & routing
- Jev-Powered Agent Runtime for JarvisCore
Muyukani Kizito says JarvisCore uses Jev in its agent runtime for RAG classification and ranking, model routing, subagent routing, and agent decisions.